Arango Introduces Contextual Data Layer for Snowflake AI Workflows
The new Arango AutoGraph and Virtual Graph capabilities aim to reduce the complexity of building knowledge graphs for enterprise AI by centralizing business context.
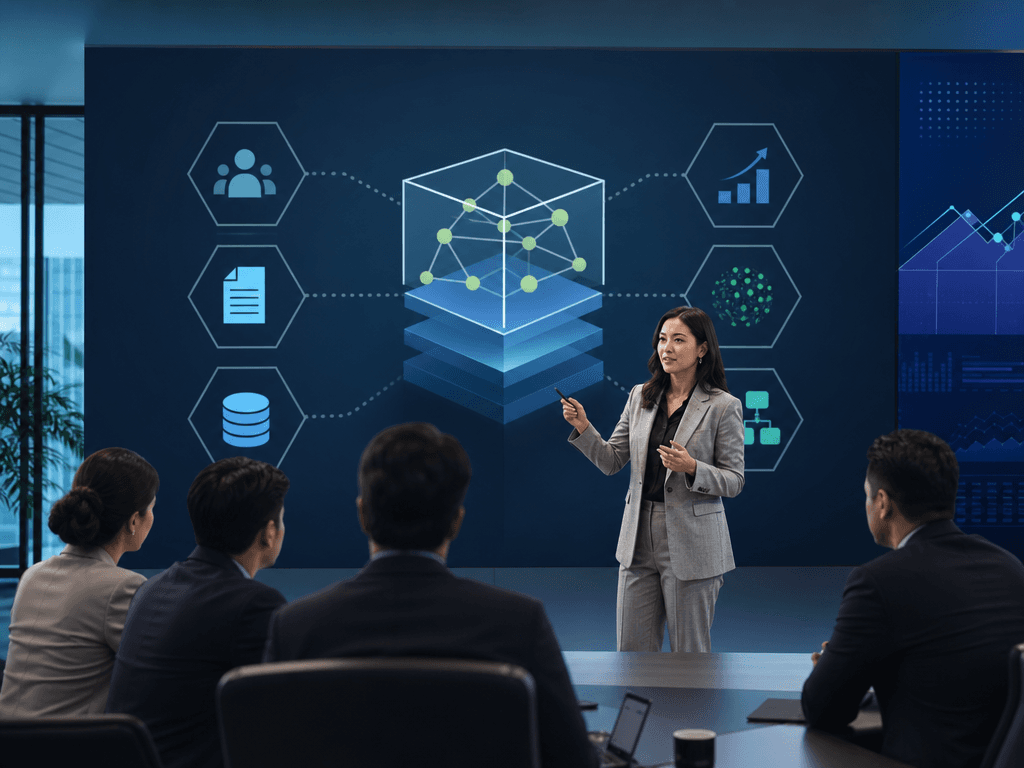
Arango unveiled its AutoGraph and Virtual Graph capabilities at the Snowflake Summit 2026, targeting the persistent challenge of fragmented business context in enterprise AI deployments. As reported by FinancialContent, the release focuses on shifting from project-specific data pipelines to a centralized, reusable contextual data layer designed to support agentic workflows.
Most enterprise AI initiatives currently suffer from high operational costs due to the repetitive reconstruction of business context for every individual application or agent. Ravi Marwaha, COO and Chief Product & Technology Officer at Arango, stated that organizations often rebuild this context for every workflow, an approach he characterizes as unsustainable for long-term scaling.
Arango AutoGraph seeks to automate the labor-intensive phases of knowledge graph development, specifically entity discovery and relationship mapping. By moving toward a no-code construction model, the tool aims to reduce the time required to transition from raw, fragmented data to production-ready AI systems.
The introduction of Arango Virtual Graph for Snowflake addresses the technical constraint of data egress and movement in cloud environments. This feature allows AI agents to query business context directly from Snowflake without requiring the duplication of datasets or the creation of additional silos.
Integration with Snowflake Cortex AI enables organizations to maintain the cloud data platform as the primary source of truth while layering graph-based context on top. This architecture is intended to support both GraphRAG and VectorRAG, providing a more structured foundation for retrieval-augmented generation than vector-only approaches.
The platform architecture relies on a graph-native multimodel foundation to unify disparate data types, including structured, semi-structured, and unstructured information. By enforcing role-based access controls and end-to-end lineage, the system attempts to bridge the gap between data engineering and AI governance requirements.
Technical leaders should evaluate whether the shift toward a centralized contextual layer introduces new dependencies on Arango’s proprietary orchestration logic. While the zero-egress approach mitigates immediate data movement risks, the long-term impact on infrastructure flexibility and vendor lock-in remains a primary consideration for enterprise architects.
The reliance on automated graph construction also warrants scrutiny regarding the accuracy of entity discovery in highly complex or legacy environments. Organizations must determine if the abstraction provided by AutoGraph sufficiently captures the nuances of their specific operational domains without requiring manual intervention.
GraphRAG implementations offer a distinct advantage over standard VectorRAG by utilizing explicit relational metadata to traverse multi-hop connections between entities. While vector embeddings capture semantic similarity, they often fail to represent the hierarchical or causal relationships necessary for complex reasoning tasks in regulated industries. By grounding retrieval in a graph structure, the system ensures that AI agents retrieve context based on defined business policies rather than simple vector proximity, which significantly reduces the risk of hallucination in high-stakes decision cycles.
Existing data governance models often struggle to maintain consistency when AI models ingest data from disparate sources without a unified schema. The Arango approach attempts to enforce lineage by mapping the provenance of every entity and relationship back to its source system, providing a verifiable audit trail for AI-generated outputs. This capability is essential for enterprises operating under strict compliance mandates, where the ability to explain the reasoning behind an AI-driven decision is as important as the decision itself.
Future deployments will likely hinge on how effectively these tools integrate with existing CI/CD pipelines and data governance frameworks. Monitoring the performance overhead of virtual graph queries during high-concurrency inference tasks will be critical for determining the viability of this architecture at scale.
Enterprise teams should prepare to benchmark the latency and accuracy improvements of GraphRAG implementations against their current vector-based retrieval systems. The transition to a persistent contextual layer represents a significant shift in how data is prepared for reasoning engines, as the explicit linkage of entities allows the model to navigate complex business logic that vector embeddings alone cannot resolve.
TAGGED
RELATED INTELLIGENCE
- DATA
Globe Telecom quantifies AI ROI through operational integration
Globe Telecom reports P1.2 billion in business benefits from AI initiatives, shifting focus from adoption to measurable financial outcomes.
- DATA
Witchbox Deploys AI-Driven Posture Analytics to Replace Legacy Hardware
Witchbox is transitioning posture assessment from high-cost hardware to mobile-based software, targeting global fitness and rehabilitation markets.
- DATA
Automating Billing Integrity to Close Revenue Leakage Gaps
Regulatory shifts toward real-time transaction monitoring demand that enterprises move from manual audit sampling to automated, continuous billing validation.