Shanghai Court Imposes Evidentiary Burden on AI Developers for Voice Training Data
The ruling establishes a new framework for proving personality rights infringement in generative AI by shifting the burden of proof to platform operators.
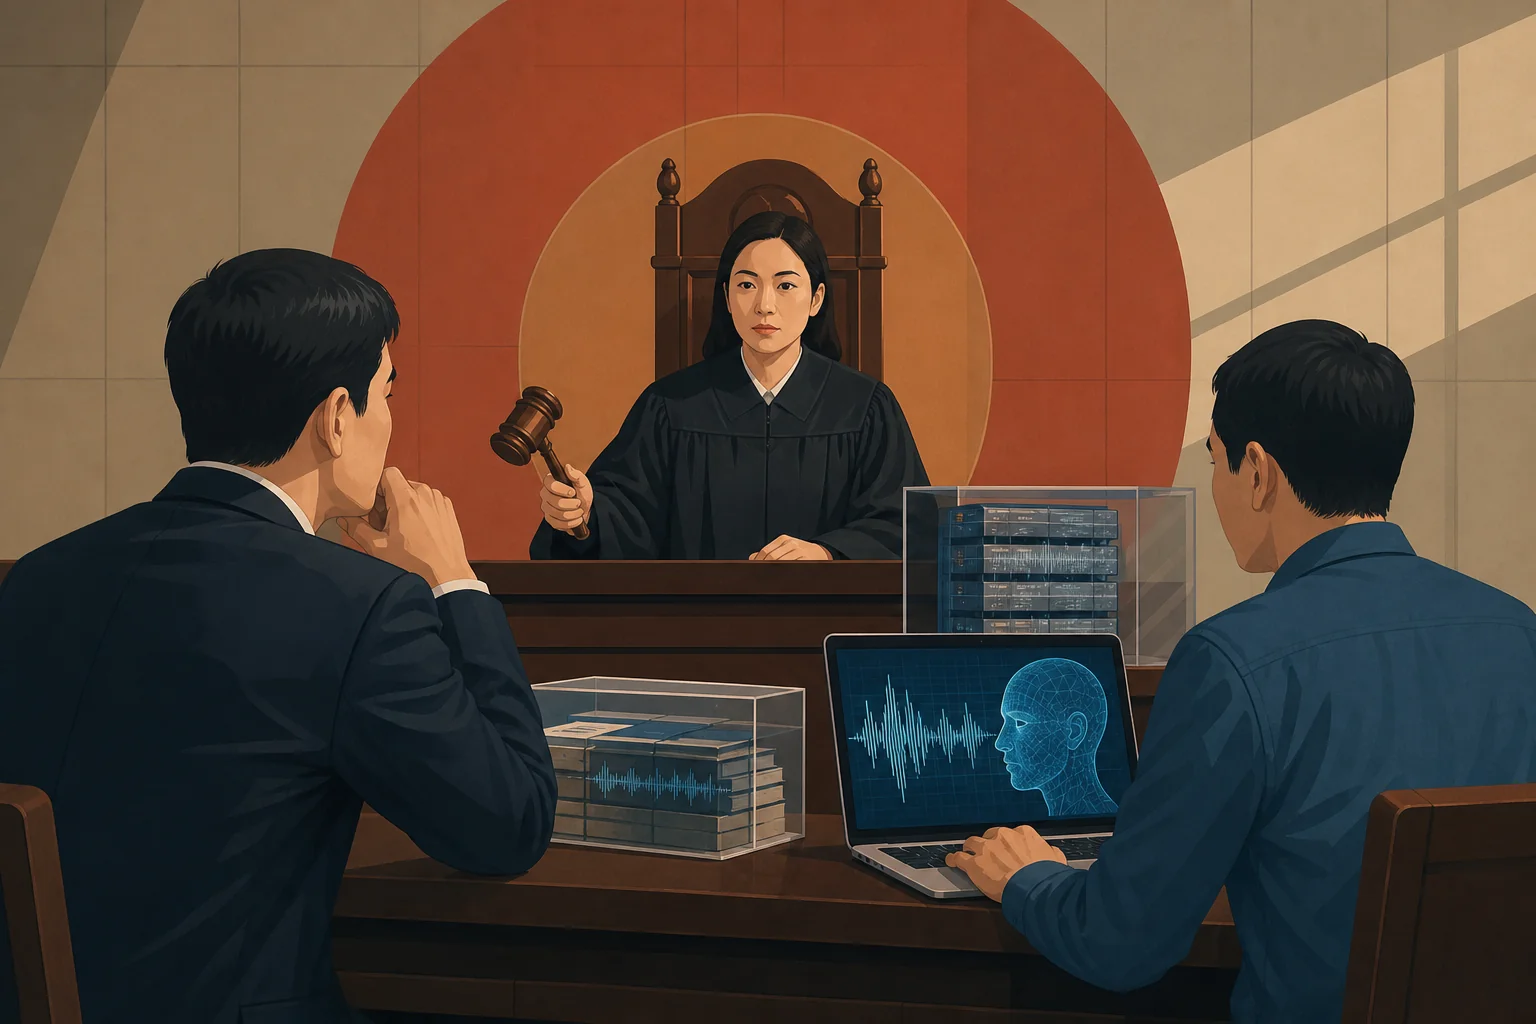
The Shanghai First Intermediate People’s Court issued a final ruling on September 29, 2026, that fundamentally alters the evidentiary requirements for personality rights litigation involving generative AI. By addressing the structural opacity of model training, the court established a mechanism to hold AI operators accountable for unauthorized voice synthesis even when the specific training corpus remains obscured.
The litigation originated from a claim filed by a voice actor, identified as Ms. Wang, who discovered her voice was replicated in a promotional campaign by an entity referred to as Company A. Ms. Wang alleged that the company utilized her publicly available work to train its AI model without authorization, leading to the creation of a synthetic voice that closely mimicked her own. Company A admitted to the generation of the audio but claimed it lacked visibility into its own training data due to staff turnover, effectively citing the black-box nature of its internal systems as a defense against liability.
To substantiate her claim, Ms. Wang presented a forensic acoustic analysis comparing the disputed audio with live samples of her voice. This analysis utilized 28 distinct formant indicators, revealing a 90% similarity between the two samples and demonstrating that the majority of indicators deviated by less than 10%. The court accepted this forensic evidence as a valid proxy for proving the unauthorized appropriation of personality interests, regardless of the underlying algorithmic methodology.
The appellate court affirmed the decision, explicitly rejecting the defendant’s argument that the lack of internal records precluded a finding of infringement. The ruling clarifies that the legal focus must remain on whether the output is recognizable as the plaintiff, rather than on the technical specifics of the training process. This shift effectively bypasses the information asymmetry that historically prevented plaintiffs from proving that their data was used in proprietary models.
Under the new evidentiary framework, a plaintiff satisfies their initial burden by demonstrating two conditions: the existence of a plausible channel through which the defendant could have accessed the plaintiff’s data and a high degree of similarity between the synthetic output and the plaintiff’s actual voice. Once these conditions are met, the burden of proof shifts to the defendant to demonstrate the lawful origin of its training material or to prove that the plaintiff’s data was not utilized.
The court’s decision aligns with Article 4 of the Supreme People’s Court’s September 2026 Opinions on AI-related disputes, signaling a broader regulatory intent to standardize accountability for generative AI operators. By treating the inability to produce training logs as an adverse failure of proof, the court has signaled that internal operational opacity is no longer a viable shield for enterprises deploying synthetic media.
This ruling highlights the increasing tension between proprietary AI development and the protection of individual personality rights within the digital ecosystem. For enterprise architects and data governance leaders, the decision underscores the necessity of maintaining rigorous provenance records for all training datasets, as the legal risk associated with undocumented data sourcing has significantly increased.
The court’s two-step approach to damages further clarifies the commercial risk for organizations using synthetic voices. In the absence of a clear licensing fee, courts will now evaluate factors such as the duration of use, the scope of dissemination, and the proportional contribution of the personality element to the commercial value of the asset. This methodology provides a clearer, albeit more stringent, rubric for calculating liability in cases of unauthorized synthetic media deployment.
Organizations must now monitor their data pipelines to ensure that all ingested content for model training is accompanied by verifiable authorization chains. The shift in the burden of proof suggests that future litigation will increasingly rely on forensic output analysis, forcing developers to maintain greater transparency regarding their training inputs to mitigate potential legal exposure.
TAGGED
REFERENCED
RELATED INTELLIGENCE
- AI
Pegasystems Q3 2026 earnings reveal enterprise AI deployment friction
The software provider faces extended sales cycles and operational hurdles as enterprise clients struggle to integrate complex AI workflows into existing architectures.
- AI
Enterprise AI Adoption Faces Operational Friction from Variable Cost Spikes
Enterprises struggle to maintain fiscal control as autonomous agent deployments outpace existing monitoring capabilities and budget governance.
- AI
Establishing Unit Economics for Enterprise AI Workflows
Enterprise leaders must shift from tracking aggregate AI spend to measuring cost-to-outcome ratios to ensure infrastructure investments deliver tangible business value.