PAW Framework Shifts AI Inference Logic to Static Local Adapters
A new research framework enables the compilation of complex AI tasks into lightweight, local adapters, challenging the necessity of large-scale runtime models for enterprise applications.
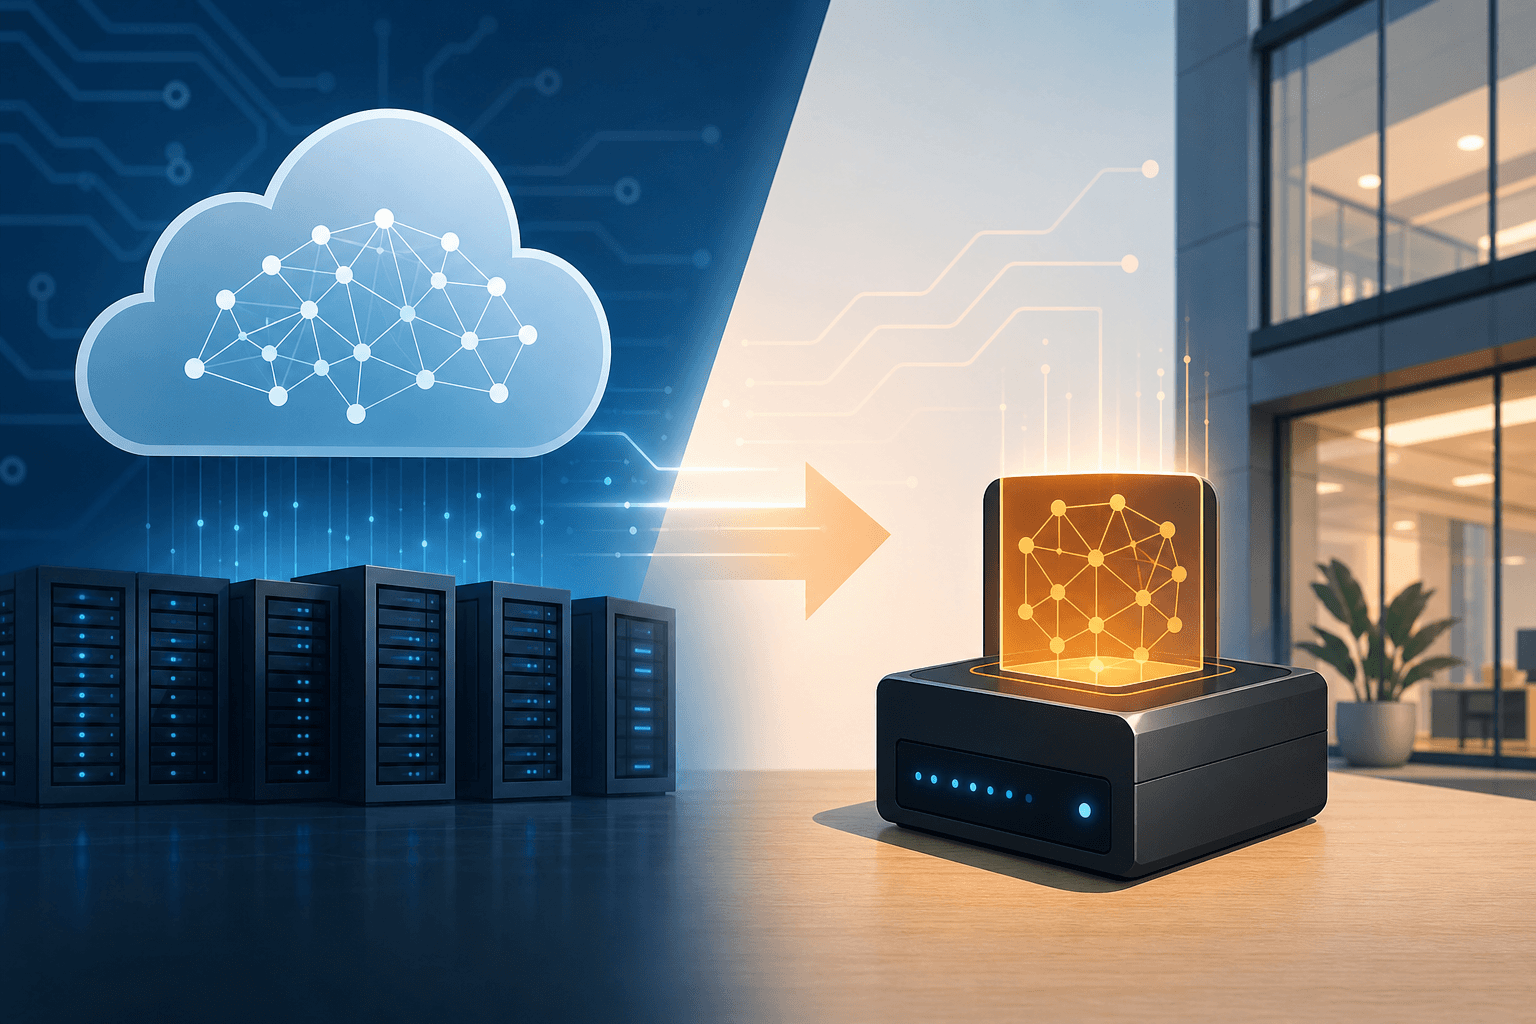
A research team from the University of Waterloo, Cornell University, and Harvard University released a framework on July 2, 2026, that decouples task logic from large language model inference. The system, known as Program-as-Weights, enables developers to compile natural-language task specifications into 23-megabyte LoRA adapter files for execution on a frozen 600-million-parameter model.
The compilation process utilizes a 4-billion-parameter model to translate task requirements into pseudo-code. This intermediate representation is then converted into a Low-Rank Adaptation adapter that captures the specific logic of the requested function.
This workflow effectively moves the computational burden of reasoning from the runtime environment to a one-time compilation phase. The resulting artifact runs locally on hardware like a MacBook M3 at 30 tokens per second without requiring external API connectivity.
Performance benchmarks indicate that the 600-million-parameter interpreter, when paired with the compiled adapter, achieves higher accuracy on fuzzy text-processing tasks than direct prompting of a 32-billion-parameter model. The system outperformed standard fine-tuning methods by 15.4 percentage points on the proprietary FuzzyBench dataset.
This shift demonstrates that task-specific performance can be decoupled from the scale of the underlying model architecture. The researchers reported that the performance gain is specifically attributable to the compiler-generated LoRA, rather than the base model architecture alone.
The framework addresses significant operational inefficiencies inherent in current API-based AI deployments. Production environments frequently rely on large models for repetitive tasks such as log triage, JSON repair, or intent classification, resulting in cumulative latency and per-token costs.
By replacing these dynamic API calls with static local adapters, organizations can eliminate network round-trips and reduce infrastructure overhead. This approach effectively lowers the total cost of ownership for AI-driven workflows by shifting the heavy compute load to a single development-time event.
Consistency remains a primary advantage of the static artifact approach. Unlike hosted API endpoints where model updates can introduce non-deterministic behavior, the compiled adapter provides a fixed, version-controlled execution path.
This stability is essential for enterprise applications where output consistency across software lifecycles is a strict requirement. The ability to audit and lock the specific adapter file ensures that the logic remains unchanged regardless of future software updates or hardware configurations.
The implementation utilizes the Qwen3-0.6B model as the frozen interpreter backbone. While this model is maintained by Alibaba Group, the local nature of the execution ensures that no data is transmitted to external servers during inference.
Enterprise architects must still evaluate the implications of using model weights from specific jurisdictions against internal data sovereignty and compliance policies. The National Intelligence Law of 2017 remains a factor for organizations assessing long-term dependencies on model releases from Chinese entities.
The architectural shift toward compile-time intelligence generation offers a viable path for deploying AI in air-gapped or latency-sensitive environments. By reducing the runtime requirement to a small, local interpreter, the framework lowers the barrier for integrating sophisticated text processing into edge devices and on-premises infrastructure.
The reliance on a larger model is strictly limited to the development phase, effectively removing the dependency on frontier-scale compute for daily operations. This model allows for the deployment of intelligent functions in environments where cloud connectivity is either unavailable or prohibited by security protocols.
Future adoption of this framework will depend on the robustness of the compiler model across broader task domains beyond the initial fuzzy-function scope. Technical leaders should monitor the evolution of the FuzzyBench dataset and the availability of alternative, non-restricted model backbones for the interpreter layer.
The transition from per-query reasoning to static adapter execution represents a necessary maturation of AI integration into production software stacks. Architects should evaluate whether their current API-heavy workflows can be migrated to this static compilation model to improve performance and reliability.
TAGGED
REFERENCED
- Qwen3-0.6B modelhuggingface.co
- National Intelligence Law of 2017dhs.gov
RELATED INTELLIGENCE
- AI
Pegasystems Q3 2026 earnings reveal enterprise AI deployment friction
The software provider faces extended sales cycles and operational hurdles as enterprise clients struggle to integrate complex AI workflows into existing architectures.
- AI
Enterprise AI Adoption Faces Operational Friction from Variable Cost Spikes
Enterprises struggle to maintain fiscal control as autonomous agent deployments outpace existing monitoring capabilities and budget governance.
- AI
Establishing Unit Economics for Enterprise AI Workflows
Enterprise leaders must shift from tracking aggregate AI spend to measuring cost-to-outcome ratios to ensure infrastructure investments deliver tangible business value.