Architecting Hybrid Inference for Enterprise LLM Workloads
Balancing on-premises hardware constraints with cloud API utility requires a strategic routing architecture based on data sensitivity and token volume.
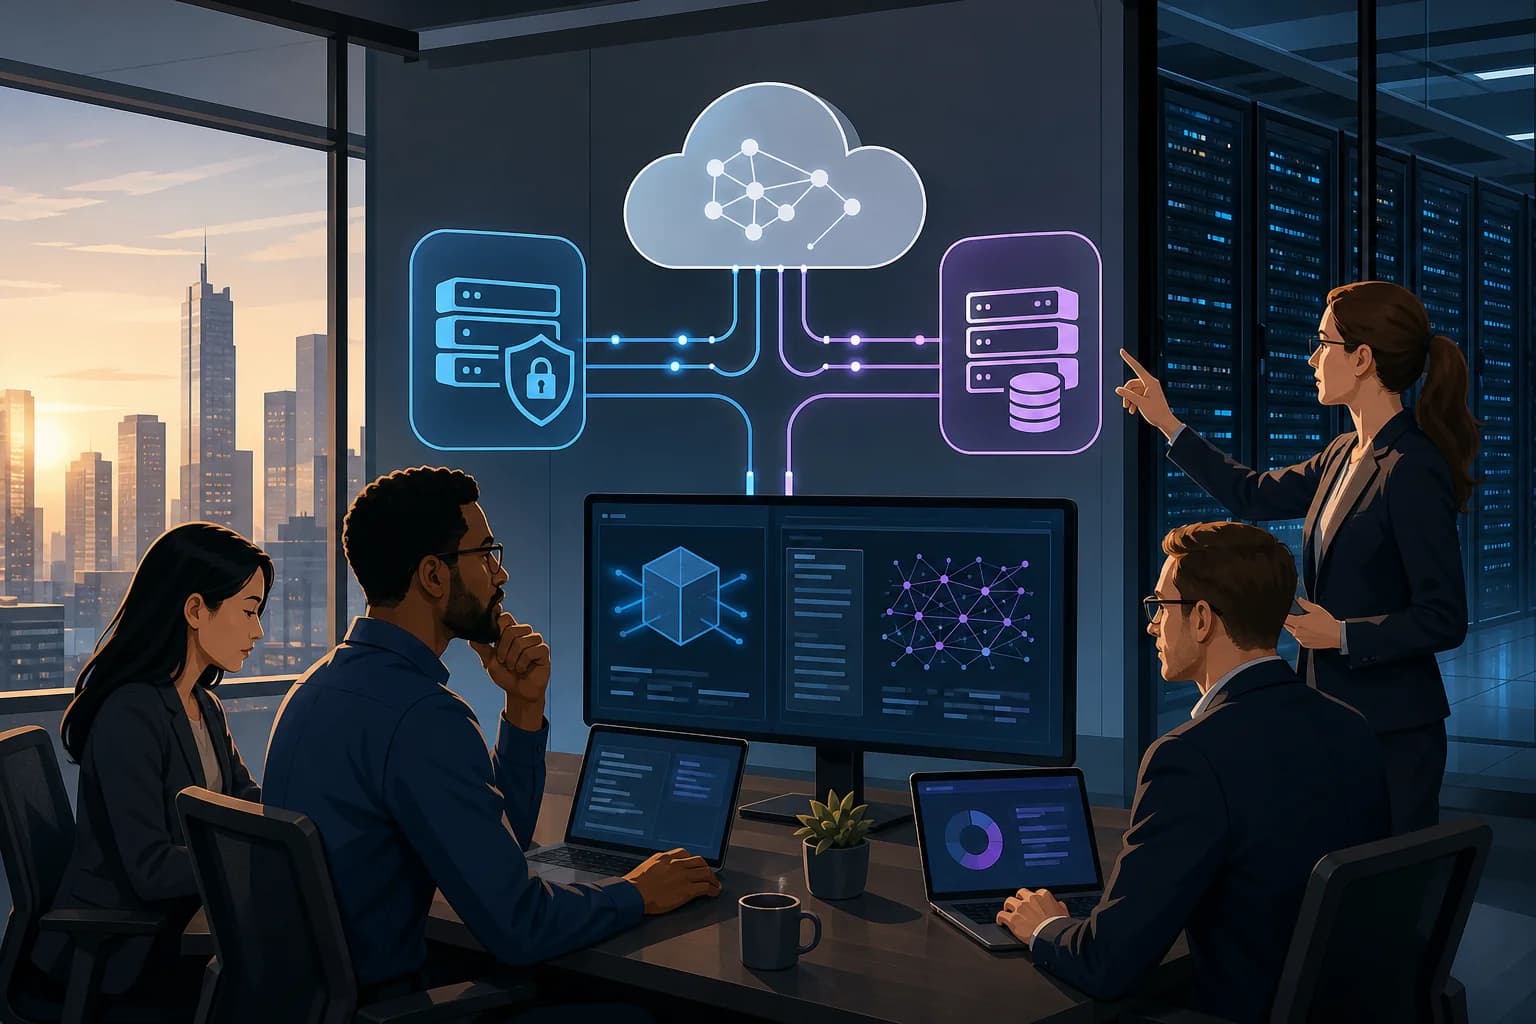
Enterprise AI strategy increasingly necessitates a hybrid deployment model that bifurcates workloads between on-premises infrastructure and managed cloud endpoints. The decision to host models locally or utilize external APIs rests on a rigorous assessment of physical memory constraints, token volume break-even points, and regulatory data isolation requirements.
Local inference requires significant capital expenditure in hardware, specifically dedicated VRAM, to maintain model weights and the key-value cache. According to technical analysis published on the developer platform Dev.to, a 70B parameter model at 16-bit precision demands approximately 140 GB of memory, necessitating high-end workstation or server-grade GPUs. Quantization techniques, such as Q4_K_M, can reduce these requirements by a factor of four, allowing smaller teams to run sophisticated models on more accessible hardware.
Mixture-of-Experts architectures further complicate the operational calculus by decoupling total parameter count from active compute overhead. These models allow for the performance characteristics of larger systems while maintaining the inference speed of smaller, denser models. Organizations must weigh these technical efficiencies against the fixed costs of hardware depreciation and ongoing power consumption.
Financial modeling reveals that replacing lightweight, high-volume classification tasks with local infrastructure rarely achieves a positive return on investment. Conversely, consistent frontier-level workloads often recover the initial capital expenditure of local hardware within a few months of operation. The primary economic driver remains the total token volume processed over the lifecycle of the infrastructure, with break-even points varying significantly by model tier.
Hardware maintenance introduces a secondary layer of operational complexity that cloud providers abstract away for their users. Beyond the initial purchase price of $2,500 for a 32 GB VRAM workstation, teams must account for electricity costs and the inevitable depreciation of physical components over a 36-month cycle. This creates a baseline monthly cost that persists regardless of whether the model is actively processing tokens or sitting idle, requiring precise capacity planning.
Memory management strategies must also account for the specific hardware bottlenecks inherent in local deployments. When VRAM is saturated, the system may resort to slower system RAM or disk swapping, which catastrophically degrades inference latency. Engineers must ensure that the model weights and the KV cache are carefully sized to fit within the physical memory limits of the GPU to avoid these performance cliffs during high-concurrency periods.
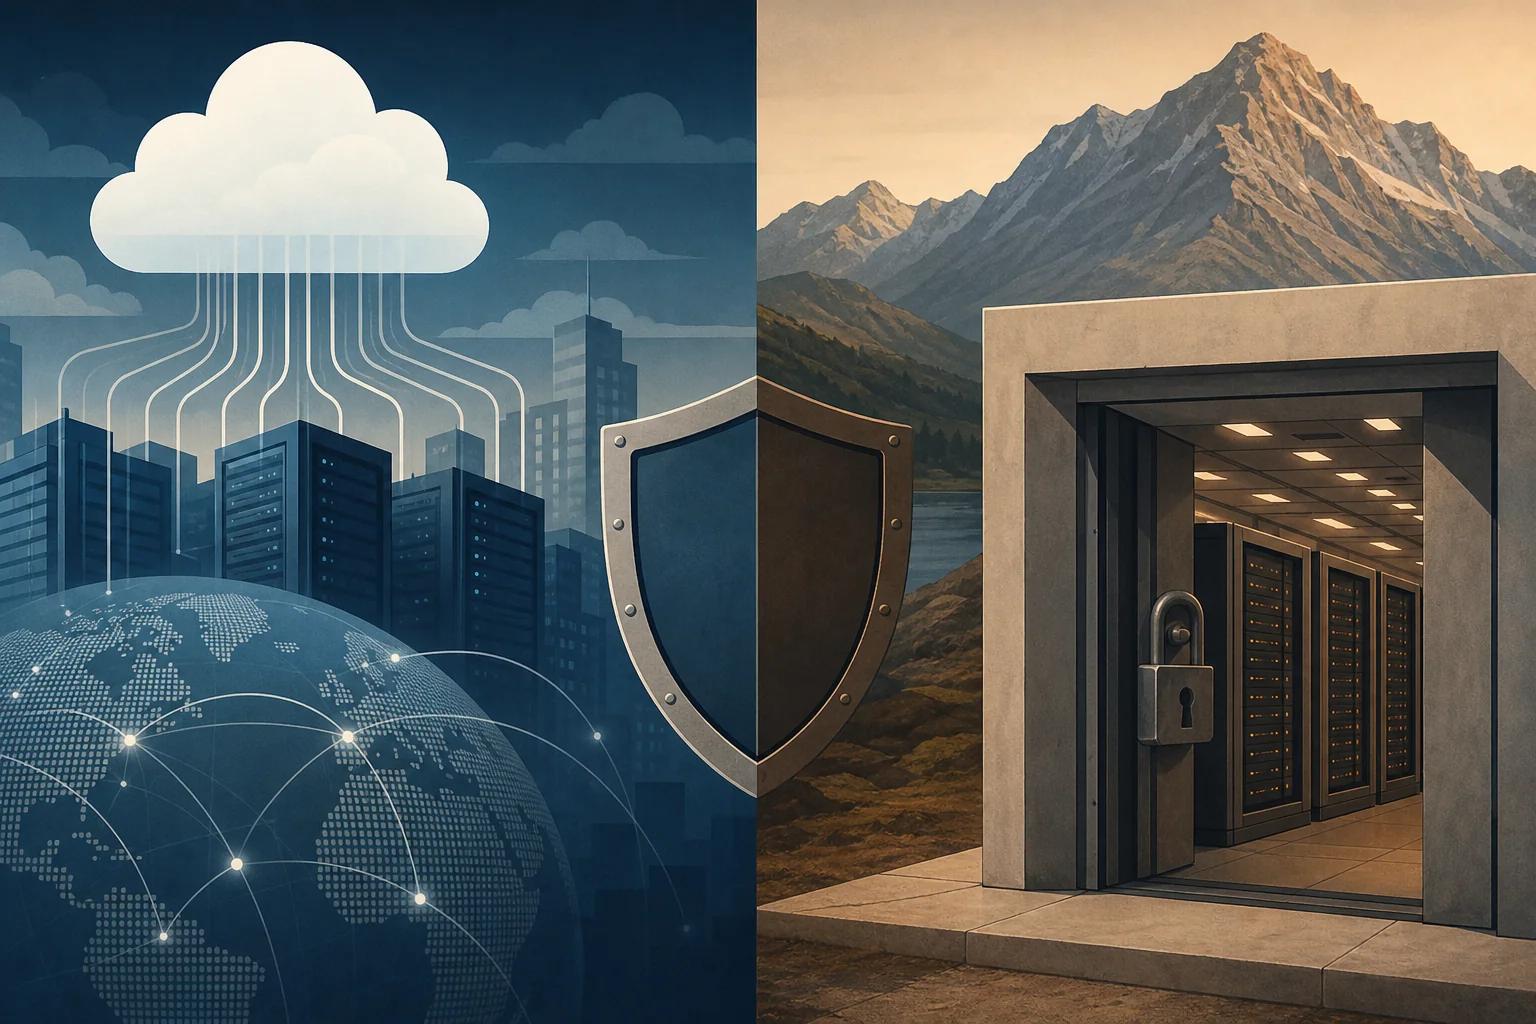
Data isolation serves as the second pillar of the architectural decision-making process, contrasting physical boundaries with legal abstractions. Local execution provides a zero-egress environment that eliminates third-party data retention risks, which is critical for regulated industries. Managed cloud providers offer contractual safeguards, yet these remain legal frameworks rather than the absolute architectural guarantees found in air-gapped environments.
The integration of long-context documents introduces significant memory pressure, as the key-value cache scales linearly with context depth. Teams often find that while base model weights fit within available VRAM, the overhead of processing massive documents can trigger out-of-memory errors. This necessitates careful monitoring of context windows to prevent service degradation during peak usage periods.
Orchestration remains a primary differentiator between local and cloud deployments, with managed providers offering superior native tool calling and structured output stability. Open-weight models frequently require custom schema enforcement and specialized prompt engineering to match the reliability of frontier-tier APIs. These hidden maintenance costs must be factored into the total cost of ownership for any on-premises deployment.
Effective routing architectures utilize a policy engine to direct workloads based on sensitivity and complexity. Routine extraction and summarization tasks are routed to quantized local runtimes to minimize egress and cost. High-order reasoning and extreme context pipelines are offloaded to commercial providers, ensuring that the most demanding tasks utilize the most capable, albeit more expensive, infrastructure.
Enterprise leaders should prioritize the development of a unified routing layer that abstracts the underlying infrastructure from the application logic. This approach facilitates the seamless migration of workloads between local and cloud environments as model capabilities and hardware costs evolve. Monitoring the delta between local inference performance and cloud API latency will remain a critical metric for long-term stack optimization.
TAGGED
REFERENCED
- 70B parameter modelgingerlabs.ai
- Mixture-of-Experts architecturesibm.com
- context depthintuitionlabs.ai
RELATED INTELLIGENCE
- INFRASTRUCTURE
AWS Scales FSx for Lustre Metadata Throughput for Intensive HPC Workloads
The cloud provider has increased metadata I/O capacity for its Intelligent-Tiering storage class, addressing a common bottleneck for large-scale research and machine learning environments.
- INFRASTRUCTURE
Architectural Shifts in Sovereign AI Deployment
Enterprises are moving beyond public cloud reliance to secure AI workloads, necessitating a fundamental redesign of infrastructure, observability, and deployment pipelines.
- INFRASTRUCTURE
Architectural Deficiencies in CMS Platforms Impacting Search Indexing
Enterprise CMS platforms frequently lack native SEO controls, forcing technical teams into unsustainable manual workarounds and reliance on insecure third-party plugins.