Architecting Self-Healing Ingress Layers for Payments Infrastructure
Moving beyond simple reflex-based automation requires a decision pipeline that prioritizes transaction integrity and auditability in high-throughput environments.
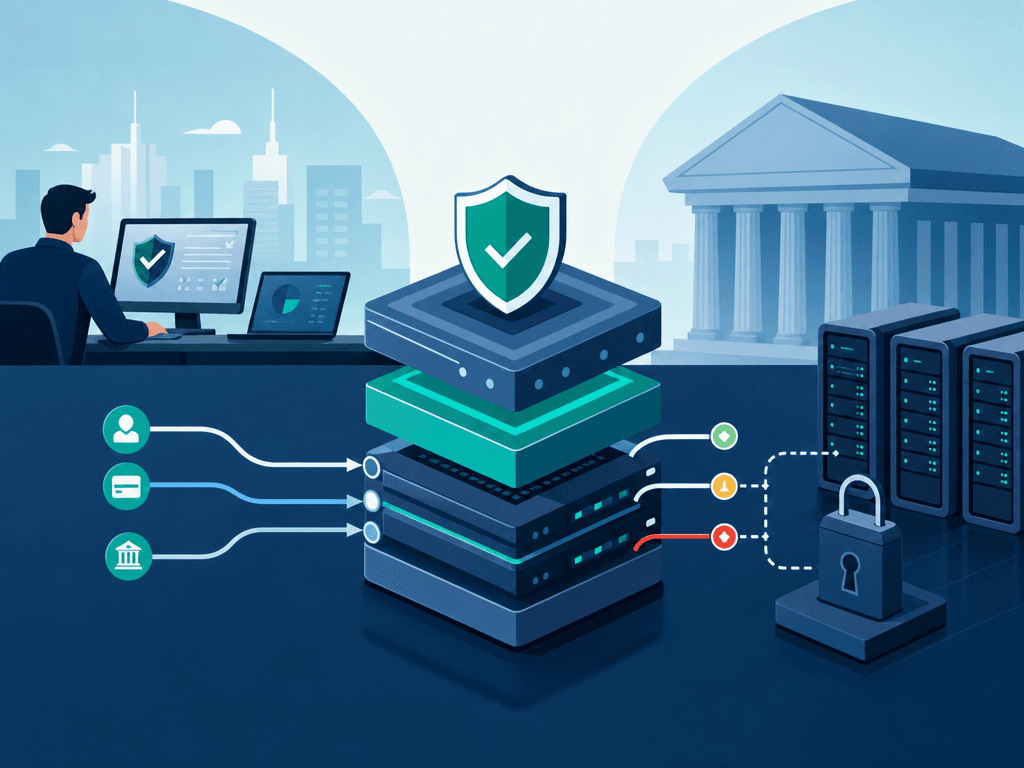
Modern ingress controllers often rely on primitive health checks that treat symptoms rather than root causes, leaving critical infrastructure vulnerable to cascading failures. A more fault-tolerant approach involves a decision pipeline that correlates telemetry into actionable hypotheses, ensuring that automated remediation acts with judgment rather than mere reflex.
The ingress tier serves as the primary convergence point for complex configurations including TLS termination, authentication, and routing logic. Because this layer intersects with changes from every engineering team, it represents the highest blast radius in the stack. Failures typically manifest as control-plane configuration errors, data-plane capacity exhaustion, or dependency-reflected issues from upstream services.
As noted in the Google SRE book, the majority of production outages stem from changes within live systems, making the gateway a frequent point of failure. When a bad route push or an expired certificate occurs, the ingress layer becomes the primary bottleneck for traffic. These control-plane failures are often global in scope and require precise, configuration-aware remediation rather than generic pod restarts.
Data-plane capacity failures present a different set of challenges, often characterized by connection-pool exhaustion or listener saturation. In these scenarios, the gateway’s own resilience features, such as retries, can inadvertently act as an accelerant by multiplying load on a degraded upstream. A remediation system must distinguish these capacity issues from configuration drift to avoid applying the wrong corrective action.
Dependency-reflected failures occur when upstream hosts or availability zones become unhealthy, forcing the gateway to handle the resulting traffic anomalies. According to technical documentation from the Envoy project, managing these failures requires sophisticated outlier detection to eject unhealthy endpoints without triggering a retry storm. Blindly restarting pods in this context often fails to address the underlying upstream sickness.
Generic auto-remediation often fails in payments-grade environments because it ignores the stateful nature of financial transactions. A simple pod restart can drop in-flight requests, potentially leading to inconsistent ledger states if idempotency keys are not perfectly managed across all layers. Retries, while intended to improve resilience, frequently act as a force multiplier for errors during periods of upstream degradation.
Remediation systems must also account for the race conditions inherent in modern deployment pipelines. Attempting to roll back a gateway configuration while a continuous delivery system is actively pushing a canary build creates a split-brain scenario that complicates recovery. Effective automation requires tight integration with deployment controllers to ensure that remediation efforts do not conflict with planned infrastructure changes.
The proposed architecture shifts from a simple trigger-action model to a directed acyclic graph of decisions. This pipeline processes telemetry from Envoy, Istio, and Kubernetes to generate ranked root-cause hypotheses before executing any corrective action. Each candidate remediation is scored based on risk and reversibility, ensuring that the system only intervenes when the probability of success outweighs the potential for disruption.
Every automated action must ship with a human-readable decision record to satisfy the requirements of regulated environments. This transparency allows engineers and auditors to verify the logic behind every intervention, effectively turning the ingress layer into an observable participant in the system’s health. If the pipeline cannot generate a high-confidence hypothesis or a valid verification contract, it defaults to a recommend-only mode that alerts human operators.
The distinction between reflex and judgment defines the difference between stable infrastructure and fragile systems. By prioritizing the preservation of in-flight work over raw recovery speed, architects can build gateways that actively protect the integrity of the data flow. This shift requires moving away from reactive scripting toward a model that understands the second-order effects of every automated command.
Leadership should monitor the maturity of their internal remediation frameworks to ensure they do not introduce new failure modes. The focus must remain on the ability of the system to explain its own actions, as unverified automation in a production environment is a liability. Future developments in this space will likely center on the standardization of these decision records across multi-cloud ingress deployments.
TAGGED
REFERENCED
- Google SRE booksre.google
- Envoy projectenvoyproxy.io
RELATED INTELLIGENCE
- INFRASTRUCTURE
BSEC Proposes Unified Back-Office Architecture to Mitigate Brokerage Fraud
The Bangladesh Securities and Exchange Commission is evaluating a centralized software framework to standardize brokerage monitoring and prevent asset misappropriation.
- INFRASTRUCTURE
Legrand Integrates Karman AI to Optimize Data Center Power Distribution
The partnership aims to reclaim stranded power capacity in high-density AI environments through edge-based intelligence.
- INFRASTRUCTURE
AI Infrastructure Choices Define Cost Attribution Limits
Enterprise architectural decisions regarding managed versus self-hosted compute environments determine the feasibility of granular AI cost governance.