AI Infrastructure Choices Define Cost Attribution Limits
Enterprise architectural decisions regarding managed versus self-hosted compute environments determine the feasibility of granular AI cost governance.
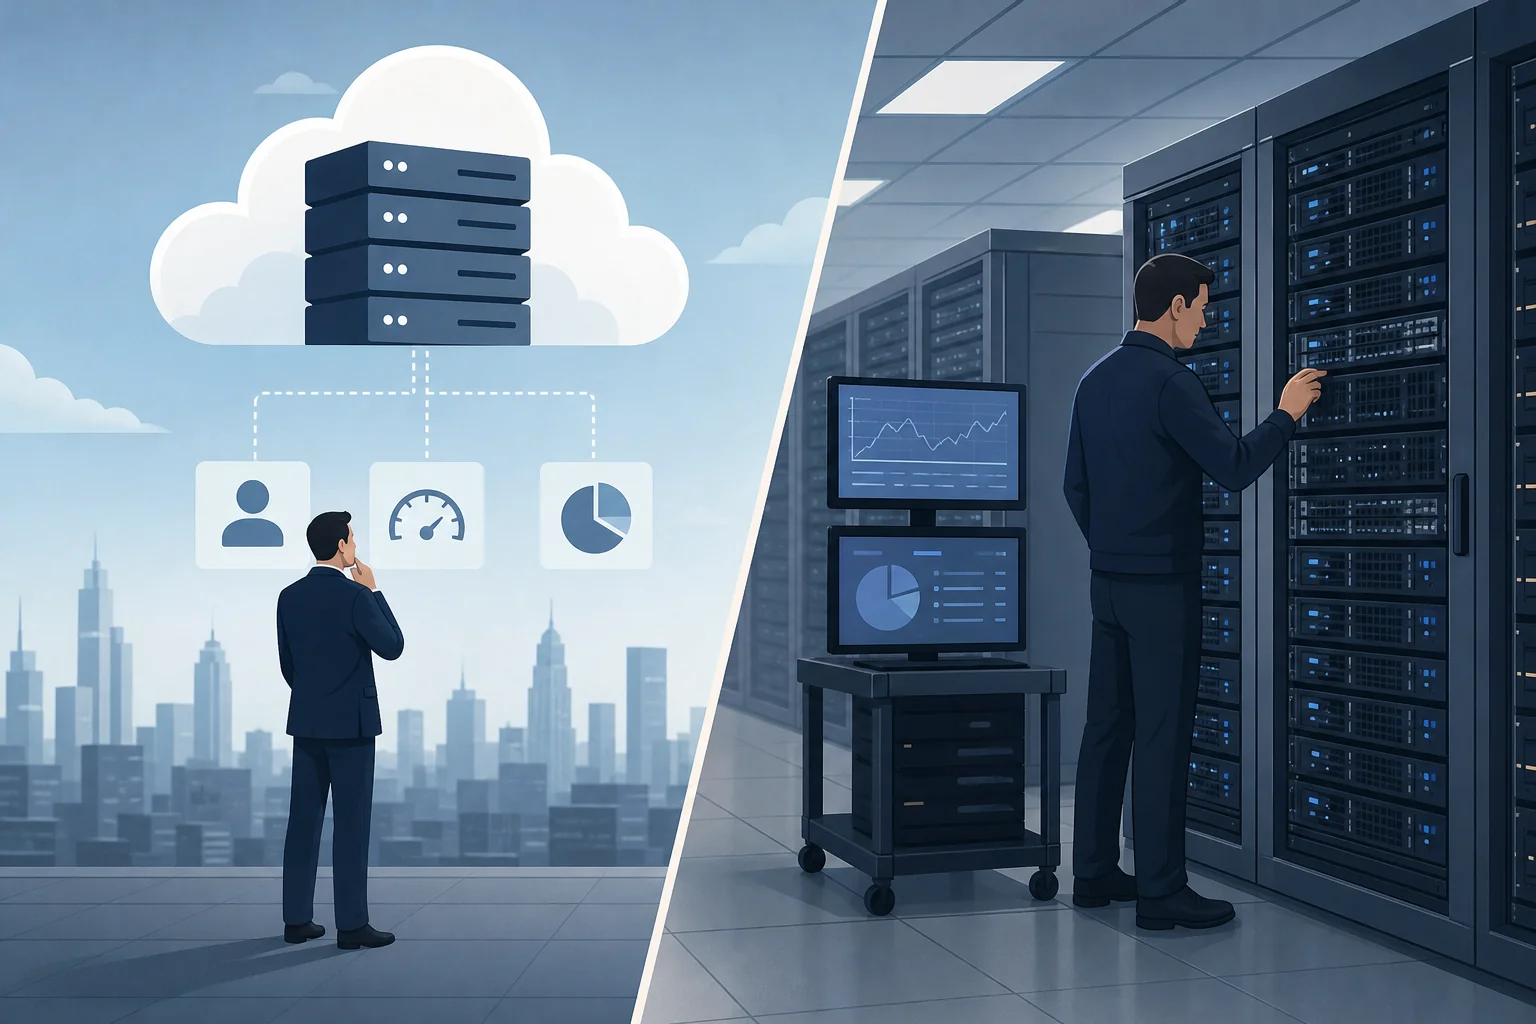
The ability to quantify the return on investment for artificial intelligence deployments is increasingly contingent upon the underlying infrastructure architecture, particularly as organizations shift from experimental pilots to production-grade agentic systems on platforms like AWS EC2 or Kubernetes. While technical methods for measuring AI costs have matured, the capacity to attribute expenditures to specific workflows remains structurally limited by the choice between managed service providers and self-managed compute environments.
Enterprise engineering teams often prioritize platform engineering merits when selecting deployment models, frequently overlooking the long-term implications for financial transparency. Managed services offer rapid scaling and reduced operational overhead, yet they abstract away the host-level access required for granular, real-time cost attribution. This creates a significant blind spot as organizations transition from experimental pilots to deploying thousands of autonomous agents.
Gartner forecasts that Fortune 500 enterprises will operate over 150,000 agents by 2028, a scale that renders traditional billing-based cost analysis insufficient. Managed services typically provide aggregated data by account or API key, which fails to map specific token consumption to individual workflows, customers, or internal business outcomes. This lack of visibility prevents organizations from isolating the cost of model inference from the supporting infrastructure, such as vector databases and prompt management layers.
Self-managed infrastructure, including virtual machines and container nodes, provides the necessary access to the host kernel required for deep observability. By utilizing eBPF technology, organizations can monitor system calls and network activity to map compute usage directly to specific processes and requests. This approach enables real-time, per-request attribution that is structurally unavailable within serverless or fully managed runtime environments like AWS Fargate.
Integrating eBPF-based monitoring into existing CI/CD pipelines allows engineering teams to automate cost-tagging without manual instrumentation of every model call. This automated approach ensures that as new agentic workflows are deployed, the infrastructure layer automatically captures the associated compute and network overhead. Such visibility is critical for maintaining accurate TCO models in environments where agent behavior is dynamic and unpredictable.
Regulated industries face additional pressure, as the inability to prove data provenance or trace execution paths within managed runtimes can pose significant compliance risks under frameworks like SOC 2 or GDPR. Proving that specific data inputs triggered specific model outputs requires a level of auditability that managed services often obscure. While managed services remain appropriate for smaller teams with limited platform maturity, the architectural decision to adopt them effectively sacrifices the ability to perform precise, infrastructure-level cost analysis.
The trade-off between managed and self-hosted environments extends beyond mere cost tracking to include model selection and routing flexibility. Managed catalogs often lag in model availability, and routing between models within a managed service frequently requires custom application code. Conversely, self-hosted environments allow for the maintenance of warm resources, reducing initialization costs and providing greater control over execution performance.
The reliance on provider-level billing cycles often masks episodic failures, such as infinite loops in agent retrieval or inefficient prompt chains that inflate costs. Real-time observability allows for immediate intervention, whereas monthly billing cycles only confirm that costs have exceeded projections without providing the context required for remediation. Engineering leaders must recognize that the choice of compute environment is a permanent architectural constraint that dictates the depth of their financial governance capabilities.
Organizations must weigh these operational advantages against the long-term necessity of maintaining visibility into AI-driven expenditures. The inability to map spend to outcomes creates a dependency on ballpark estimates, which inevitably leads to downstream financial errors. Leaders should evaluate whether their current cloud strategy permits the integration of kernel-level monitoring tools or if they are locked into managed runtimes that preclude such visibility.
Monitoring the evolution of agent-based workloads will be essential as the complexity of these systems continues to outpace the reporting capabilities of standard cloud provider billing interfaces. Future-proofing AI investments requires a shift toward architectures that prioritize observability at the infrastructure layer. Establishing this visibility now will prevent the accumulation of technical debt that would otherwise arise from unmonitored and unoptimized autonomous agent deployments.
TAGGED
RELATED INTELLIGENCE
- INFRASTRUCTURE
BSEC Proposes Unified Back-Office Architecture to Mitigate Brokerage Fraud
The Bangladesh Securities and Exchange Commission is evaluating a centralized software framework to standardize brokerage monitoring and prevent asset misappropriation.
- INFRASTRUCTURE
Legrand Integrates Karman AI to Optimize Data Center Power Distribution
The partnership aims to reclaim stranded power capacity in high-density AI environments through edge-based intelligence.
- INFRASTRUCTURE
Standardizing LLM Infrastructure for Enterprise Reliability
Transitioning from fragmented AI application development to a centralized platform model reduces hallucination rates and improves operational visibility.